Research · 2024 – 2025
LLM-Coordination
A benchmark for testing how well LLM agents coordinate with a partner in cooperative games, published in Findings of NAACL 2025.
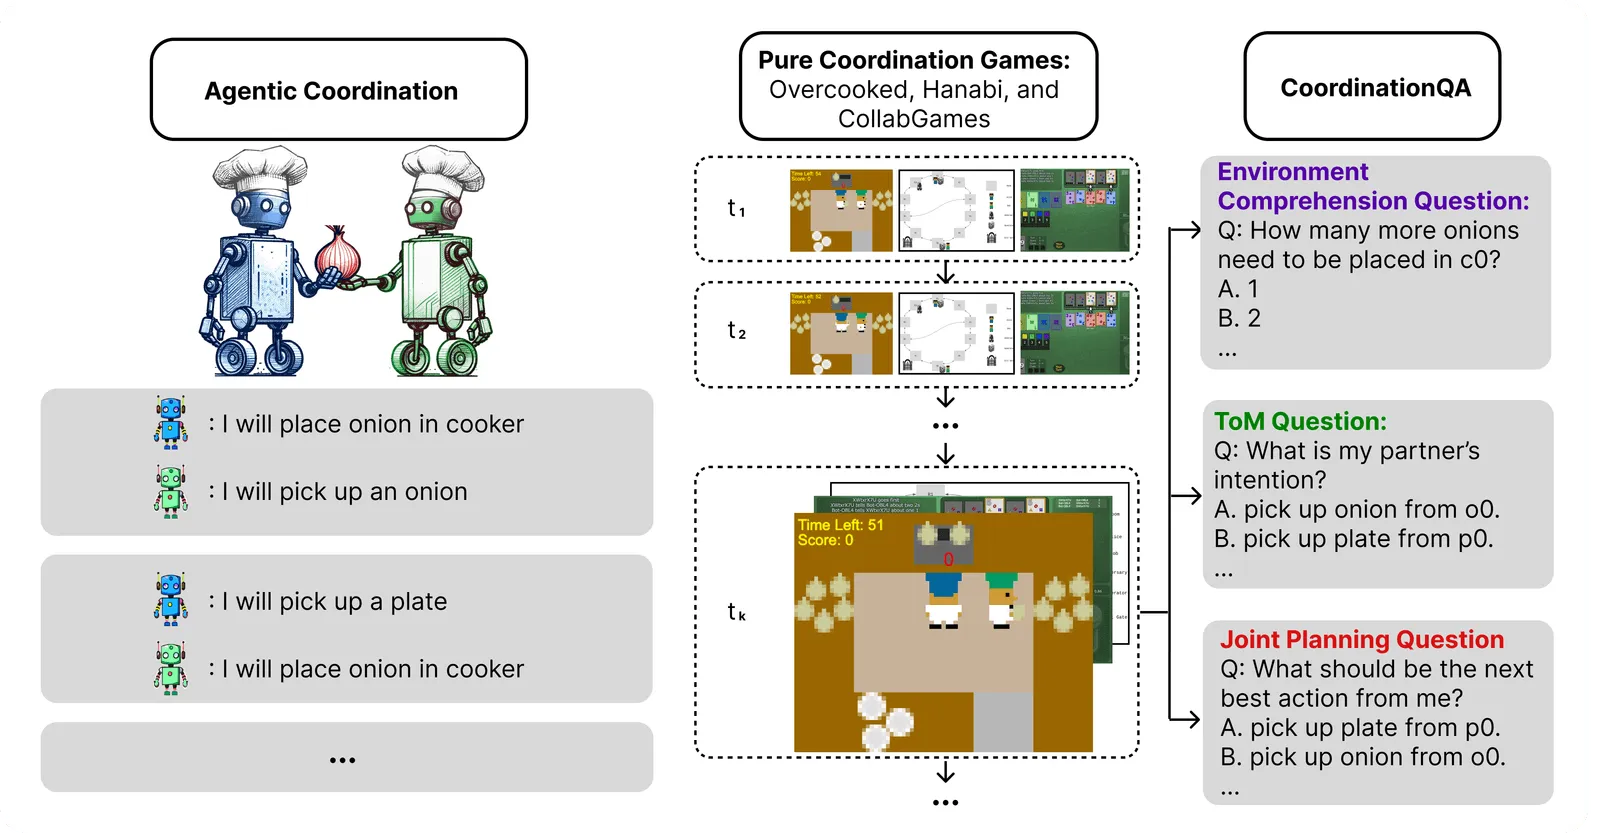
Large language models are increasingly used as agents, but most evaluations test them alone. LLM-Coordination asks a different question: can an LLM agent work with a partner, reading their intent and planning around them, in games where the only way to win is to cooperate?
The benchmark has two parts:
- Agentic coordination. LLM agents play full games of Hanabi, Overcooked-AI, Collab Capture, and Collab Escape with a partner.
- CoordinationQA. Multiple-choice questions taken from game states, which separate three abilities: understanding the environment, reasoning about the partner (theory of mind), and joint planning.
My part
I worked on this in Prof. Xin Eric Wang’s ERIC Lab at UC Santa Cruz. I helped develop the benchmark suite across the four games, running and analyzing agent evaluations, and I’m a co-author on the paper.
Paper
Saaket Agashe, Yue Fan, Anthony Reyna, Xin Eric Wang. LLM-Coordination: Evaluating and Analyzing Multi-agent Coordination Abilities in Large Language Models. Findings of NAACL 2025.